Petra Patterson · 27 September 2026
Unpacking the Role of Algorithmic Personalization in Sustaining Long-Term User Loyalty Within Specialized Applications
Specialized applications such as fitness trackers, language learning platforms, and niche productivity tools rely on algorithmic personalization to analyze user data patterns and deliver content that aligns with individual behaviors, and this approach has been shown to extend session durations while reducing churn rates over multi-month periods according to industry analyses. Data from multiple sectors indicates that these systems process inputs like interaction frequency, completion rates, and preference selections to refine outputs dynamically, which creates feedback loops that encourage repeated use without requiring manual adjustments from the user side.
Core Mechanisms Driving Personalization
Machine learning models form the foundation of these systems as they segment users into cohorts based on shared traits and then generate predictions about future actions, while collaborative filtering techniques compare one person's activity against similar profiles to suggest relevant features or content modules. Reinforcement learning elements adjust recommendation weights in real time based on immediate feedback signals such as clicks or skips, and this combination allows applications to move beyond static rules toward adaptive strategies that evolve with each user interaction cycle. Observers note that when these models incorporate contextual signals like time of day or device type, the resulting suggestions gain precision and support deeper integration into daily routines.
Links to Retention and Loyalty Metrics
Retention statistics collected across specialized app categories reveal that users exposed to consistent personalization features demonstrate higher return rates at the 30-day and 90-day marks compared with those receiving generic interfaces, and longitudinal tracking shows sustained subscription renewals when recommendation accuracy exceeds certain thresholds. The Federal Trade Commission report from September 2026 highlights how transparent data practices in personalization engines correlate with lower complaint volumes and stronger user trust signals over time. Application developers often integrate A/B testing frameworks to measure these effects, isolating variables such as notification timing or content variety to quantify their contribution to loyalty indicators like net promoter scores and feature adoption depth.
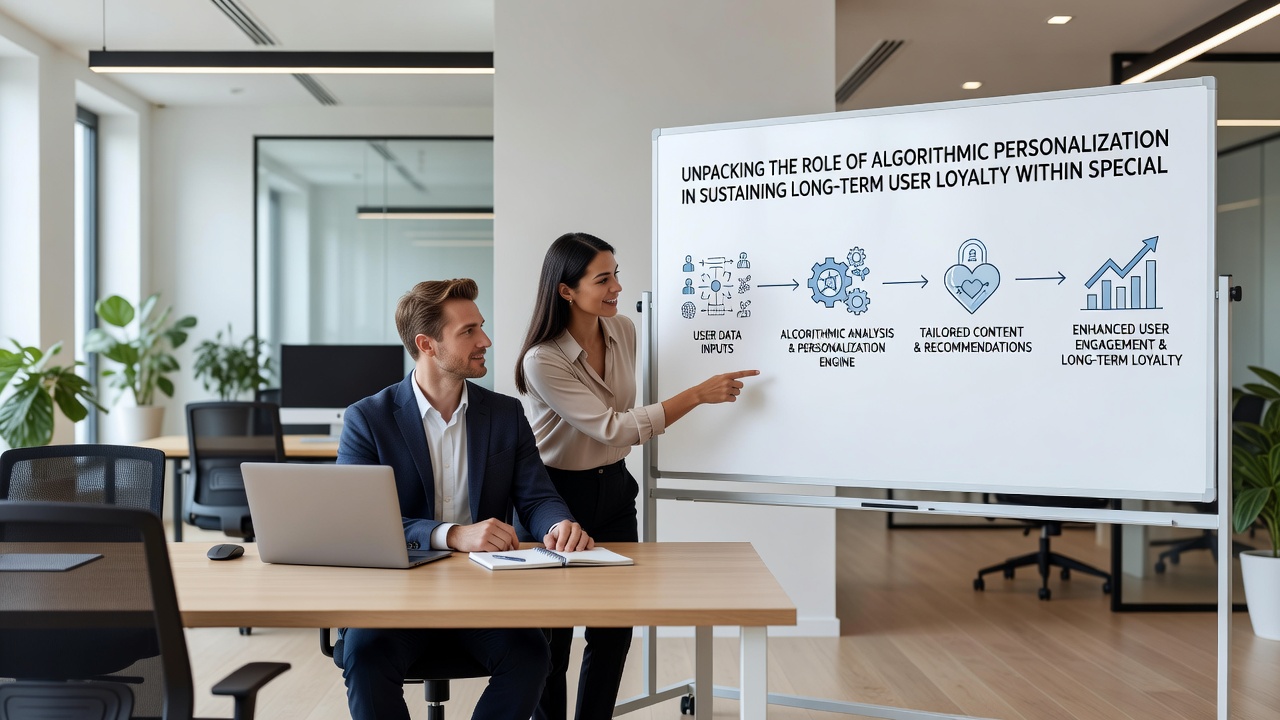
Case examples drawn from language learning environments illustrate how spaced repetition algorithms personalize vocabulary drills according to past error patterns, which leads to measurable improvements in completion streaks and community participation levels. Similar patterns appear in fitness applications where workout plans adapt to recovery data and goal progress, resulting in extended active user lifespans documented through platform telemetry.
Technical and Regulatory Considerations
Privacy regulations across regions require explicit consent mechanisms and data minimization protocols before personalization algorithms can access sensitive behavioral logs, and compliance frameworks in the European Union and Canada emphasize audit trails that document how user information influences recommendation outputs. Developers address these constraints by employing on-device processing for certain computations or anonymized aggregation methods that preserve utility while limiting individual exposure. Research from academic institutions shows that when users receive clear explanations of how their data shapes experiences, acceptance rates for personalization features increase and drop-off during onboarding decreases.
Scalability challenges emerge when handling diverse user bases because models must balance computational costs against accuracy gains, and specialized applications often adopt hybrid architectures that combine cloud-based training with edge inference to maintain responsiveness. Industry reports indicate that continuous model retraining cycles, typically performed weekly or monthly, help counteract concept drift as user populations shift their habits or preferences.
Evidence from Broader Implementation Patterns
Cross-platform comparisons demonstrate that applications incorporating multi-signal personalization achieve stronger cohort retention than those relying on basic rule sets, and this advantage compounds when combined with community features or progress visualization tools. A study conducted by researchers affiliated with the University of Toronto examined retention curves across several specialized categories and found consistent associations between personalization depth and lifetime value metrics. These findings align with telemetry gathered from apps released after 2024, where iterative refinements to recommendation engines produced incremental lifts in daily active user figures without proportional increases in marketing spend.
Conclusion
Algorithmic personalization operates as a central component in the architecture of specialized applications by transforming raw behavioral data into adaptive experiences that align with user trajectories, and available evidence points to measurable effects on engagement duration and renewal likelihood. As technical capabilities advance and regulatory environments evolve, the methods used to implement these systems continue to incorporate safeguards around consent and transparency. Observers tracking developments through 2026 note that ongoing refinements in model efficiency and cross-regional compliance will shape how these tools sustain loyalty within targeted user segments over successive product iterations.